
Official statement
Other statements from this video 2 ▾
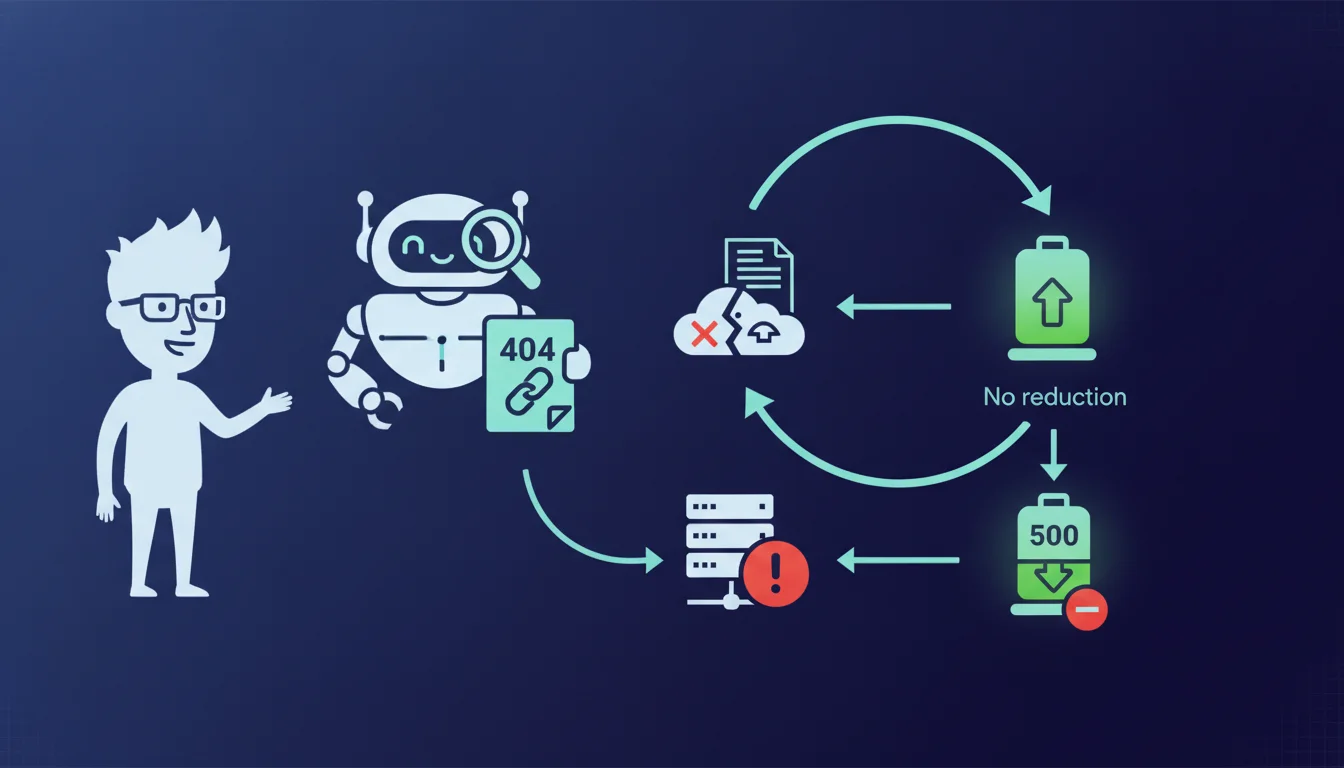
Google states that 404 errors do not impact the crawl budget, unlike 5xx server errors that indicate critical malfunctions. This distinction is game-changing for technical audits: there’s no need to panic over usual 404s on deleted URLs. The focus should be on server stability, not obsessively eliminating every missing page.
What you need to understand
Why does Google make this distinction between 404s and 5xx?
The logic behind this position lies in the very nature of the web. Content disappears, URLs change, products are pulled from catalogs. A 404 simply indicates that a resource no longer exists at this location, providing legitimate information for the search engine.
5xx errors fall into another category: they indicate that the server is malfunctioning and cannot respond properly. Googlebot does not know if the page exists or not; it only knows that the server is unstable or unreachable. This uncertainty causes the algorithm to slow down crawling to avoid overloading a server already in trouble.
What does this really change for the crawl budget?
The crawl budget represents the number of pages that Googlebot is willing to explore on your site within a given timeframe. This quota depends on your server's capacity and the value that Google assigns to your content.
When Googlebot encounters a 404, it logs that this URL no longer exists and moves on to the next one. No penalties, no slowdown. The crawler continues to do its job as usual. However, a flurry of 500 errors triggers a protection mechanism: Googlebot spaces out its requests to avoid worsening the situation.
In what situations can 404s still be problematic?
This statement doesn’t mean that all 404s are harmless. A massive volume of 404s on actively crawled URLs often reveals a structural problem: broken pagination, faulty internal linking, outdated sitemaps.
The real issue with 404s isn’t the crawl budget, but the waste of it. If Googlebot spends its time on dead URLs instead of exploring your new content, you have an architecture problem, not an HTTP code problem.
- Normal 404s (out-of-stock products, old deleted articles) do not affect crawling
- 5xx server errors trigger a slowdown in crawling to protect your infrastructure
- An unusual volume of 404s often signals an internal linking issue or a poorly maintained sitemap
- Crawl budget is wasted when Googlebot heavily explores low-value URLs, whether dead or not
- Priority should be on server stability and optimizing crawl towards strategic pages
SEO Expert opinion
Does this statement align with field observations?
In essence, yes. Empirical tests show that a site with clean and consistent 404s does not experience crawl slowdowns. Googlebot has handled these situations without issue for years.
The key point of concern lies in the nuance that Google doesn’t communicate sufficiently: context matters. A site with 50 pages and 5 normal 404s poses no problem. A site with 10,000 pages and 8,000 404s in the logs reveals a structural malfunction that will inevitably impact crawling efficiency, even if Google doesn't impose a direct penalty on the budget.
What blind spots does this official position leave?
Google remains vague about soft 404s — those pages that return a 200 status but display error content. These cases waste more budget than a true 404 because Googlebot must load the entire page before realizing it contains nothing of value.
The statement also does not specify the behavior regarding 404 redirects. If your server consistently redirects 404s to the homepage with a 301 or 302, you create a different problem: dead URLs remain in the index with inappropriate content. [To verify]: the exact impact on the crawl budget in these hybrid configurations remains poorly documented.
Should we really ignore all 404s then?
Let’s be honest: no. This statement doesn’t give you a free pass to neglect your architecture. 404s do not penalize the crawl budget, but they often reveal leaks in your internal linking.
Each 404 crawled from an active page on your site signals a broken link that you should fix. The real work involves differentiating external 404s (backlinks to old URLs, user bookmarks) from internal 404s that point to issues you directly control.
Practical impact and recommendations
What should you prioritize monitoring in your crawl logs?
Focus on server stability above all. 5xx errors represent the real threat to your crawl budget. A spike in 500 or 503 errors triggers an immediate slowdown for Googlebot.
Analyze the crawl frequency of 404 URLs. If Googlebot keeps returning to the same dead pages, it means your internal linking or sitemap still references them. Fix these links instead of focusing on the HTTP code itself.
How to effectively clean up without wasting budget?
Identify the 404s crawled from active pages on your site. These are the only ones that deserve immediate action: fix the link, apply a 301 redirect if the URL had value, or simply remove it if the link provides no benefit.
For 404s coming from external sources (obsolete backlinks, user favorites), assess the real traffic volume. If an old URL still receives significant visits, redirect to the closest content. Otherwise, let the 404 do its job without feeling guilty.
What concrete actions can be taken right now?
Audit your XML sitemap and remove all URLs returning 404s. This is the most common source of waste: you explicitly signal Google to explore dead pages.
Set up monitoring for 5xx errors with real-time alerts. Unlike 404s, these errors require immediate action before they impact your crawl capacity. Managing these aspects can be time-consuming and need specialized expertise in server architecture and crawl optimization. Engaging a specialized SEO agency often helps quickly identify bottlenecks and implement sustainable solutions suited to your infrastructure.
- Clean the XML sitemap of all 404 URLs
- Fix internal links pointing to dead pages
- Set up monitoring for 5xx errors with automatic alerts
- Check for the absence of soft 404s (empty pages returning a 200)
- Analyze logs to identify frequently crawled 404s and correct their origin
- Implement 301 redirects only for 404 URLs with significant residual traffic
❓ Frequently Asked Questions
Un site avec beaucoup de 404 peut-il quand même bien ranker ?
Faut-il rediriger systématiquement toutes les URLs en 404 ?
Combien de temps Google continue-t-il à crawler une URL en 404 ?
Les soft 404 sont-elles traitées comme des vraies 404 pour le budget de crawl ?
Quelle différence entre une erreur 503 et une 500 pour le crawl ?
🎥 From the same video 2
Other SEO insights extracted from this same Google Search Central video · duration 8 min · published on 28/10/2026
🎥 Watch the full video on YouTube →
💬 Comments (0)
Be the first to comment.