
Official statement
Other statements from this video 4 ▾
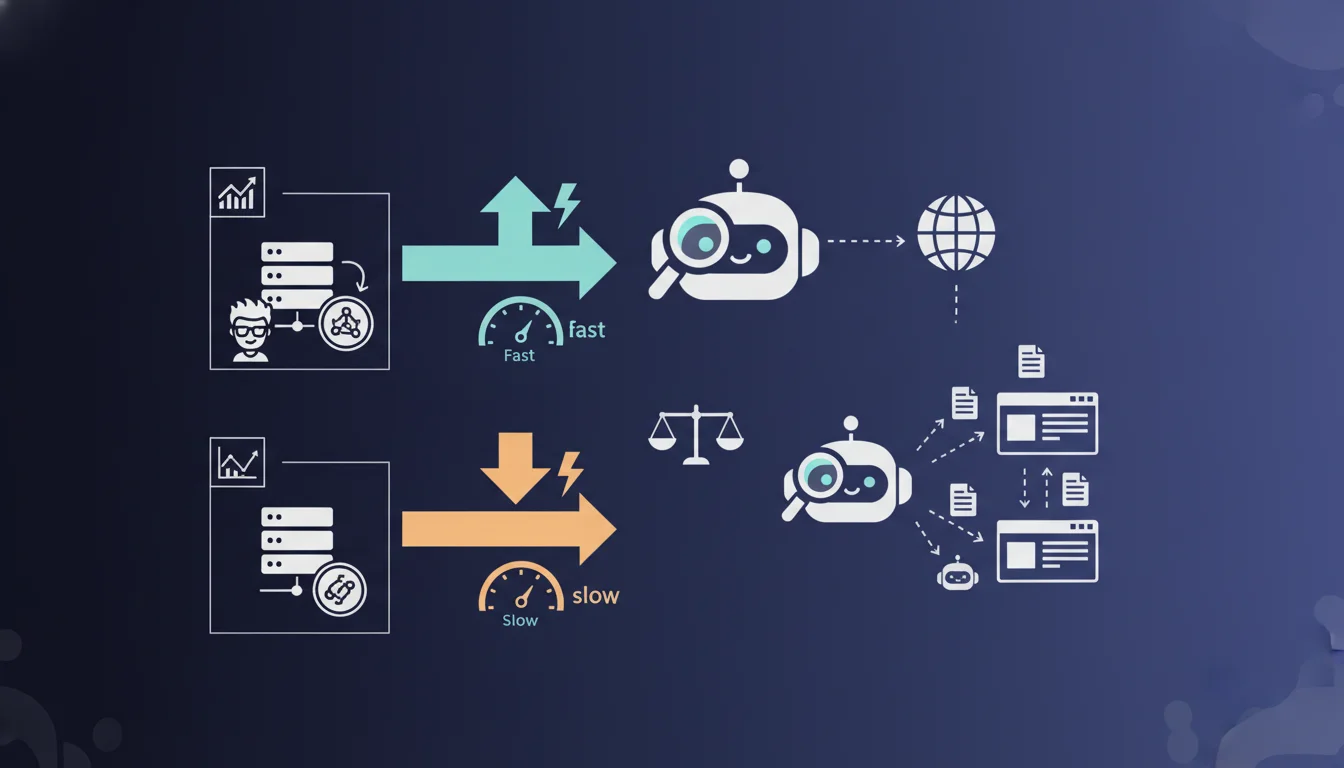
Google automatically adjusts crawl speed based on the perceived health of the server. A CDN that speeds up responses sends a positive signal: crawlers gradually increase their frequency. Conversely, degrading response times trigger a slowdown to protect the infrastructure. In practice, technical performance is not just a ranking factor; it also determines the volume of pages crawled.
What you need to understand
Does Google actively monitor server health?
Google's automated systems integrate mechanisms for continuous monitoring of web server responsiveness. Each crawler request records response time, HTTP errors, and other load signals. This telemetry then informs crawl intensity decisions.
This isn't simply a static calculation based on the Crawl Budget declared in Search Console. The engine adapts its behavior in real-time according to what it observes. If the server handles the load and responds quickly, Googlebot thinks it can push harder without risking destabilization.
How does a CDN enhance the perception of site health?
A Content Delivery Network distributes resources across multiple geographic points of presence. The result: response times mechanically decrease, especially for crawlers coming from different Google data centers.
This improvement sends a clear signal: the infrastructure manages the load with ease. Google interprets this speed as a capacity to absorb more requests. It’s a virtuous cycle: better infrastructure → faster crawl → more complete and fresh indexing.
What happens when response times degrade?
The engine applies a principle of automatic caution. As soon as responses slow down, crawlers reduce their frequency to avoid further overloading the server. This may seem protective, but the immediate consequences are clear: fewer pages crawled, less frequent indexing of updated content.
This logic also applies in cases of repeated 5xx errors or timeouts. Google has no interest in crashing a site: it prefers to slow down rather than risk complete unavailability. For an e-commerce site with thousands of product listings, this slowdown can delay the indexing of new stock or urgent promotions.
- Crawlers adjust their speed according to the real-time server health signals observed.
- A CDN speeds up responses and triggers a gradual increase in crawl.
- Frequent slowdowns or errors lead to an immediate decrease in crawl intensity.
- The Crawl Budget is not fixed: it evolves according to the perceived technical performance by Google.
- This adaptation protects the infrastructure but may delay indexing if the server cannot keep up.
SEO Expert opinion
Is this statement consistent with field observations?
Yes, and it's one of the few points where Google is transparent about an operational mechanism. Professionals deploying a CDN frequently observe a rise in crawl in the following weeks, visible in Search Console (Crawl Stats report). It’s not instantaneous: Google tests gradually, increasing in increments.
However, the statement remains vague about the trigger thresholds. At what point of additional latency does the slowdown activate? How many consecutive 5xx are enough to cut off the flow? [To verify]: no official documentation quantifies these limits, and they likely vary based on the site's historical PageRank and update frequency.
What are the risks of excessive interpretation?
Some deduce that a CDN boosts ranking. This is a classic confusion between correlation and causation. The CDN improves crawl and Core Web Vitals, which indirectly influence ranking. But slapping a CDN on a slow site without optimizing the backend won’t solve anything: Google will end up crawling the slow, dynamic pages, and the problem will resurface.
Another trap: thinking that a fast-responding server is enough. If the content is duplicated, thin, or irrelevant, Google won’t crawl more pages just because of speed. Technical health is necessary but not sufficient. The engine also optimizes its crawl based on the perceived value of URLs.
In what cases does this rule not fully apply?
On sites with very low authority or recent ones, even with a flawless CDN, crawl remains limited. Google prioritizes its resources for established sites with a history of fresh, relevant content. A brand new WordPress blog on Cloudflare won’t suddenly crawl 10,000 pages per day.
Similarly, certain types of content trigger a selective crawl independent of server speed: dynamically generated pages with URL parameters, infinitely paginated content, non-canonical e-commerce facets. Google may deem these URLs low priority even if they respond in 50 ms.
Practical impact and recommendations
What should you concretely do to optimize crawl through server speed?
Start by auditing server response times (TTFB) in Google Search Console, under the Crawl Stats section. If the graph shows regular spikes or gradual degradation, it's the first warning signal. Cross-check with your server logs to identify slow URLs.
Deploy a modern CDN (Cloudflare, Fastly, AWS CloudFront) in reverse proxy mode for all HTML, not just static assets. Configure an intelligent caching policy: short TTLs on dynamic pages, long TTLs on evergreen content. Monitor automated purges during updates to avoid serving stale content to crawlers.
What mistakes should you absolutely avoid?
Don’t think that a free CDN will solve everything. Free plans often limit the number of requests or bandwidth, which can paradoxically slow down the crawl during peaks. Prefer an infrastructure sized to handle hundreds of simultaneous requests from Googlebot.
Also, avoid accidentally blocking CDN IPs in your firewall or .htaccess. Ensure that Googlebot can access cached versions and that the HTTP headers (Cache-Control, Vary, ETag) are consistent. A CDN that consistently returns 304 Not Modified on modified content skews the freshness signal.
How can you measure the real impact on crawl after deployment?
Monitor in Search Console the evolution of the total number of pages crawled per day over 4 to 6 weeks. A gradual increase confirms that Google is ramping up its allocation. Also, compare the average time between publication and indexing for new content (blog posts, product listings).
On the infrastructure side, track the percentage of CDN hits vs origin specifically for Googlebot. If 95% of the crawler’s requests still hit the origin server, the CDN is not configured properly. Ideally, the cache should absorb 80% or more of the bot traffic.
- Activate a CDN with HTML caching to reduce the TTFB seen by Googlebot
- Check in Search Console the evolution of the number of pages crawled per day after deployment
- Configure cache headers (Cache-Control, Vary, ETag) to avoid stale content
- Size the CDN plan according to the expected crawl volume, not just human traffic
- Monitor 5xx errors and timeouts to anticipate automatic slowdowns
- Exclude sensitive pages (cart, customer account) from the CDN cache to avoid leaks or errors
❓ Frequently Asked Questions
Un CDN gratuit comme Cloudflare Free suffit-il pour booster le crawl ?
Combien de temps faut-il pour voir l'effet d'un CDN sur le crawl ?
Le crawl ralentit si on désactive temporairement le CDN ?
Un serveur ultra-rapide sans CDN peut-il obtenir le même crawl qu'avec CDN ?
Faut-il mettre toutes les URLs en cache CDN, y compris les pages dynamiques ?
🎥 From the same video 4
Other SEO insights extracted from this same Google Search Central video · duration 8 min · published on 11/11/2026
🎥 Watch the full video on YouTube →
💬 Comments (0)
Be the first to comment.